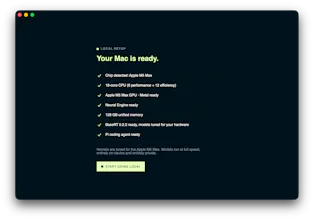
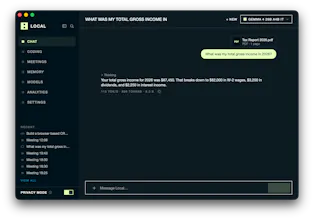
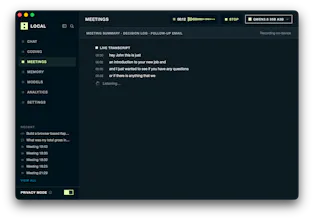
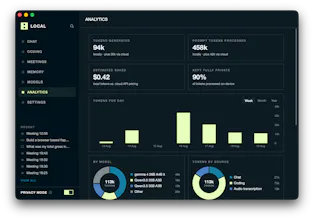
I've been meaning to run a local model on my Mac for a while but always bounced off the setup - picking the right quantization, figuring out what my hardware could actually handle, getting a decent frontend on top of it. Local just skips all of that. It looked at my machine, picked models that actually run well, and I had a working local chat in a few minutes with zero config decisions to make. The speed difference versus the same models run through a generic wrapper is very noticeable too, meeting notes transcribe close to real time on my M-series Mac.





 LM Studio
Local
Product Hunt
Congrats on the launch. I'm curious if you ran tests on different hardware specifications and if you noticed an ideal setup for certain models and what the bare minimum requirements are.
Cool! Does it only work on Apple Silicon processors? I have a 2020 MacBook Air, the last model with an Intel chip. Would it work on mine?
BaseRT
If you're curious about the engine that makes Local the fastest AI inference app on Apple silicon, check out BaseRT and the research behind it: https://www.basecompute.co/research
BetterClaw
LLM costs can get messy really quickly. Having a smarter way to balance price and performance feels like a problem worth solving.