Launched this week

Claude Haiku 5.5
Anthropic's fastest and most capable Haiku yet
430 followers
Anthropic's fastest and most capable Haiku yet
430 followers
Claude Haiku 5.5 is Anthropic's fastest and most capable small model, built for high-volume, cost-sensitive tasks like summarization, classification, coding subagents, customer support, and browser use.



Launch Team

TinyFishSearch, fetch and browse for AI agents. Claim 30% bonus!
Promoted
Anthropic's Claude Haiku 5.5 is a faster, lower-cost model designed for high-volume and speed-sensitive workloads.
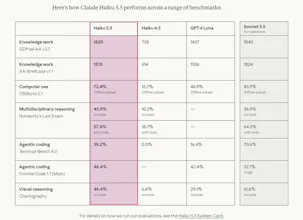
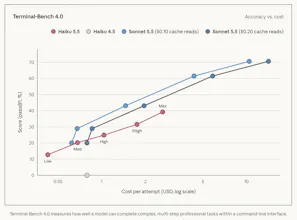
What makes it different: It combines stronger performance with significantly lower pricing and is the first Haiku model with an adjustable effort setting.
Key features:
• 90% lower pricing than Haiku 4.5 for prompts up to 100K tokens
• Anthropic's fastest model to date at standard speed
• Adjustable effort settings to balance cost and intelligence
• Stronger performance across computer use, reasoning, knowledge work, and coding
• Built for tasks like summarization, classification, coding subagents, customer support, and browser use
• Available through Claude Platform, AWS, Google Cloud, and Microsoft Azure
Who it's for: Developers and teams running high-volume, cost- or latency-sensitive AI workloads.
Explore Claude Haiku 5.5
P.S. I hunt the latest and greatest launches in tech, SaaS and AI, follow to be notified → @rohanrecommends
Already added this model into my VM stack :)
the cost sensitive task and browser use in haiku 5.5 make it look pretty practical for everyday work
I always run data through this tier first when I set up web scrapers. It really helps cut down execution times by half when dealing with messy HTML, from live retail sites
The 90% less for pricing is superb!
the adjustable effort setting is the part I care about most here, most "fast and cheap" model releases make you pick a model tier upfront and live with it for the whole workload. being able to dial effort per request means a voice agent could run cheap on routine turns and bump it up only when the conversation actually gets ambiguous, instead of overpaying for every single turn just to cover the hard ones
An adjustable effort setting is the detail that stands out, since it lets you dial down cost for high volume jobs and back up only when a task needs it. Ninety percent lower pricing than the last Haiku for prompts under 100K tokens is a strong pitch for summarization and support workloads. Does the effort setting change latency as much as it changes cost?