Launched this week

Prefer
The execution layer for AEO
289 followers
The execution layer for AEO
289 followers
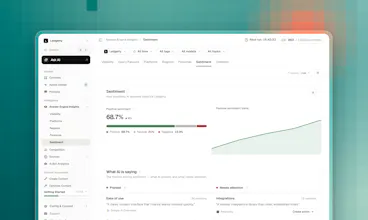
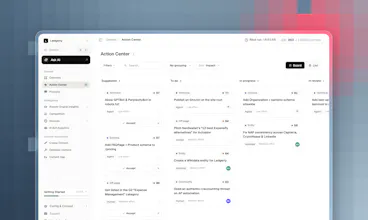
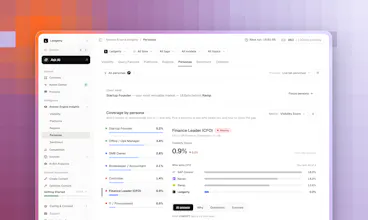
AEO should not be another dashboard. Prefer works at the execution layer, helping brands understand how ChatGPT, Claude, Gemini and Perplexity talk about them, identify where they are missing, and take action to improve their visibility. Turn AI search insights into action with autonomous agents. Less reporting. More doing.




Love the idea, thanks!
Hey @jordangibbs thanks for flagging it, and sorry it hit you minutes after you signed up.
Nothing was wrong with your account. A bug on our side was making pages fail at random for a small number of people yesterday. It is fixed and the fix is live, so things should load normally now. Your project, your data and your report are all intact.
You are right about the support email as well, we have sorted that out now. Let me know if you face anything else.
@mandar_sawant Nice, updated my comment. Appreciate the fixes
closing the gap not just measuring it is the right angle. usefull stuff 👍 agencies or in-house teams using it more?
Congrats on the launch! How do you tell if an action actually moved a brand's visibility? Model answers change a lot between runs, so I'm curious how you separate real lift from noise.
@sahil_kathpal1 That’s exactly why we don’t treat a single model response as the metric.
Prefer continuously runs the loop, tracking how each model changes its preferred sources, taking action, and measuring the impact over time.
And it doesn’t stop once you get the citation or recommendation.
It keeps monitoring and taking action to help you retain that visibility as the models and their sources change.
Congrats on the launch, Javed and the Prefer team. Tying each Action Center fix to the prompts it should move is the right shape. The launch copy leads with Claude, but the pricing page only lists Claude Sonnet 4 via API on Enterprise, so is Claude tracking coming to self-serve tiers? Lots of B2B buyers research vendors in Claude, and API answers can differ from what people see in the app.
Treating AEO as something you act on rather than another dashboard to read is the right instinct, since most brands know they are invisible in AI answers but not what to do about it. Checking how ChatGPT, Claude, Gemini and Perplexity each describe a brand is a practical angle. Curious how you measure whether the actions actually moved visibility.
@karimbenkeroum
Yes, this is exactly where the loop becomes important.
We do not measure an action in isolation.
We establish a baseline for the prompts and queries that matter, then continuously re-run them across ChatGPT, Claude, Gemini and Perplexity.
When we take an action, we track what changes afterwards:
- Whether the brand gets mentioned or recommended
- Which sources start getting cited
- Which competitors are gaining or losing visibility
- Whether the model changes its preferred sources
- Whether the improvement persists over multiple runs
If we see movement, we can connect it back to the actions taken. If we do not see movement, the system goes back into the loop and identifies what is still missing.
And this matters because AI search is not static.
A source that gets cited today may not be preferred a few weeks from now.
So for us, the goal is not simply to increase visibility once.
It is to continuously improve it, measure the impact, and then protect the gains we have made.
That is the part we think is fundamentally different from another AEO reporting dashboard.